Running language models on your own hardware · Ollama, vLLM, llama.cpp
Workstations for Local LLMs
Running models privately instead of paying per token, where the model has to fit in video memory before speed matters at all.
Task by task
What Local LLMs actually needs
Fitting the model
Needs: Video memory
At 4-bit quantisation a model needs roughly half a gigabyte per billion parameters, plus room for the context.
Speed
Needs: Memory bandwidth on the card
Once the model fits, the card's memory bandwidth sets how fast it answers.
Serving several users
Needs: More memory for context
Each concurrent user needs their own context cache.
The same advice applies to Ollama, vLLM, llama.cpp and LM Studio.
Hardware at a glance
What to buy for Local LLMs
Our picks
Machines we recommend for Local LLMs
| Specification | |||
|---|---|---|---|
| Our take | Runs 8B to 30B-class models at 4-bit for one person, privately and with no per-token cost. | A 32GB card with more memory bandwidth, for faster answers and longer context on the same models. | 96GB across two cards. Runs 70B-class models with room for long context, shared across a team with vLLM. |
| Processor | AMD 16 Core Processor | AMD 24 Core Processor | AMD 64 Core Processor |
| Graphics | ZOTAC 24 GB Vram graphics card | Palit 32 GB Vram graphics card | HPE 96 GB Vram graphics card |
| Memory | 64GB High speed memory | 128GB High speed memory | 384GB High speed memory |
| Storage | 3TB total | 6TB total | 17.28TB total |
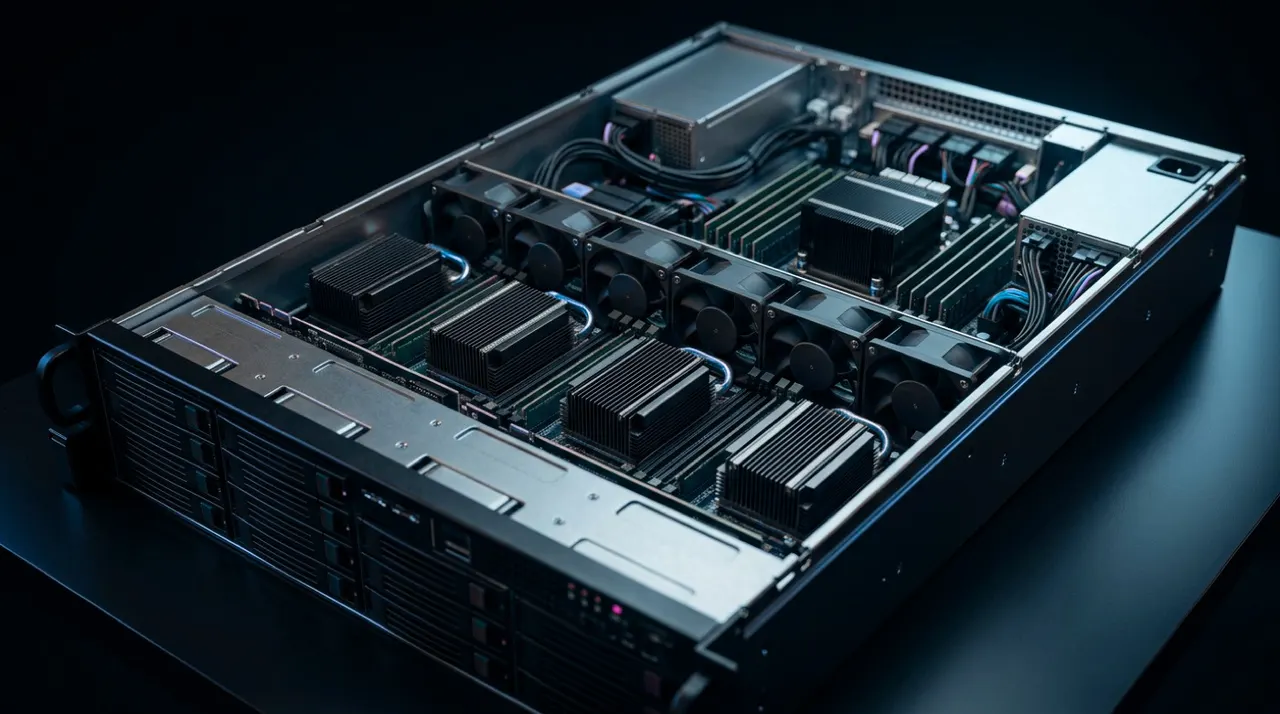
| Form | Tower, desk-side | Tower, desk-side | 4U rack |
| Actions |
Questions
Local LLMs hardware questions
What size model can I run on 24GB?
At 4-bit quantisation, models up to roughly 30B parameters with a moderate context. 7B to 14B models run comfortably with long context.
Can I run a 70B model locally?
Yes, with about 40GB of video memory at 4-bit before context, so in practice 48GB or more. Our two-card server has 96GB, which leaves room for long context and several users.
Is local cheaper than an API?
For steady daily use, usually, and your data never leaves your building. For occasional use an API is cheaper. We can help you work out the break-even for your usage.
Why buy from us
91checks
Checked before it is quoted
Fit, power, cooling and memory, on every build.
72hours
Burned in before it ships
Full load for three days, so faults show up here.
1working day
An engineer replies
With a specification and a quote for your work.
1number to call
Supported in Pakistan
From Islamabad, delivered nationwide, with warranty handled here.
Other AI & machine learning software
Want an engineer to size it for your Local LLMs work?
Tell us the size of your largest model. An engineer replies within one working day.