Fusion Grid AI 300
- GPU nodes
- 8
- Accelerators
- 16 × 48GB
- Pooled memory
- 768GB
What is in it
- Login, head and controller nodes2x
- Fabric switches2x2 × NDR 400Gb/s
- Accelerated compute nodes8x2 accelerators each
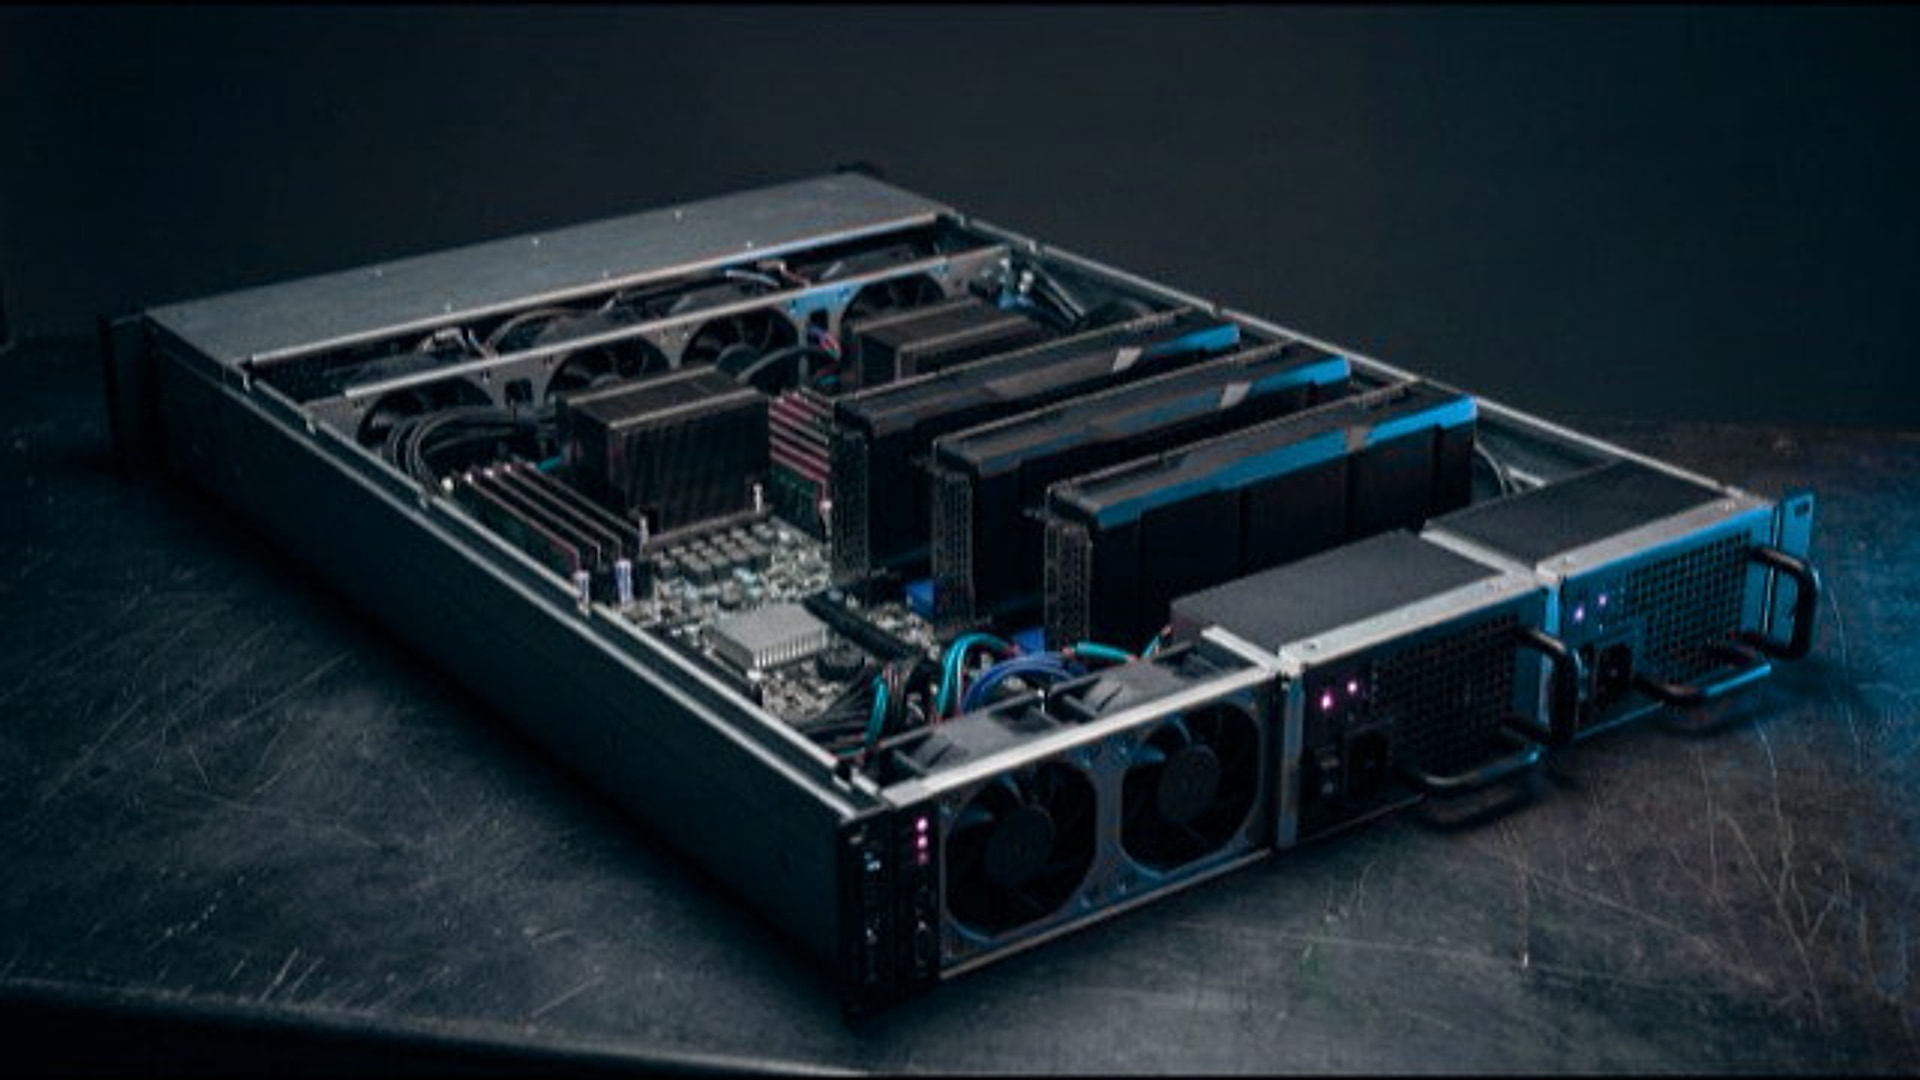
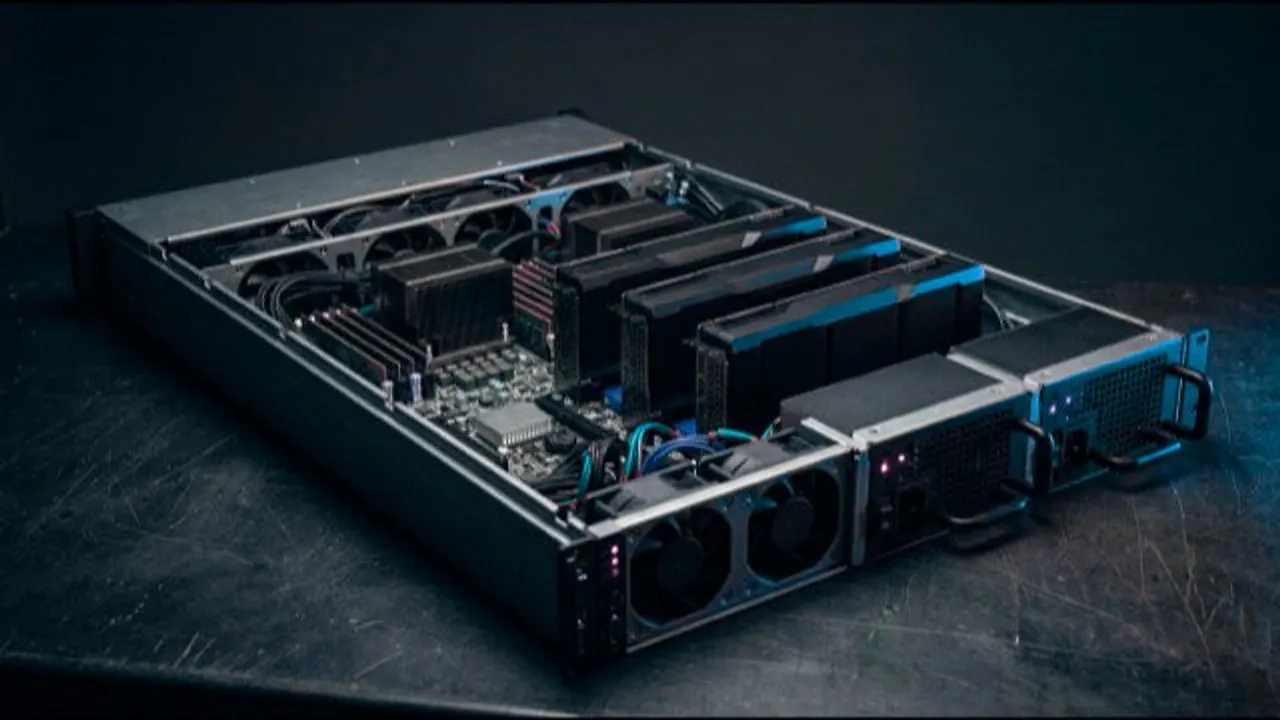
What arrives, across one cabinet, racked, cabled and burned in before it ships. The nearest single server we sell is the Fusion Rack AI 300, shown in the photograph, with every part listed.
Why this cluster
Sixteen L40S across 8 nodes, pooling 768GB of accelerator memory. A 400Gb/s NDR link per card gives gradient exchange its own path, and each node has 30TB of Gen5 NVMe as a dataset cache, because at this scale data loading is what falls behind first.
Made for your workflow
Your cluster, connected
Explore the hardware, shared capacity and connections that bring your cluster together.
- Compute nodes
- 8 nodes
- 1 cabinet · AI and ML training
- Multiple machines share the workload across your team or applications.
- GPU memory
- 768GB
- 16 × 48GB · Aggregate across GPUs
- Distributed AI workloads use memory across cards; capacity per GPU still matters.
- Connecting the nodes
- 2 × NDR 400Gb/s
- Specified network fabric
- The interconnect moves data between nodes so the cluster can work together.
- Shared storage
- 400TB NVMe
- Specified filesystem capacity
- A shared home for the files, datasets and results your nodes need to access.
Hardware platform
How the cluster comes together
Network fabric2 × NDR 400Gb/s · 2 switches
- Control & access2 login, head and controller nodes
- GPU compute8 accelerated compute nodes
Each square represents one node. Final capacity and cabinet layout are sized to your site.
What it is for
AI and machine learning need different things from a simulation cluster. Accelerator memory and speed matter more than processor cores. The processors prepare data, and the accelerators do the work. Video memory usually decides everything, because a model that does not fit does not run slowly. It does not run at all. The network is sized so parameters and gradients move without holding training back, and the data pipeline is sized to keep the cards busy, since a slow loader leaves your most expensive hardware idle.
Both sizes of AI and ml trainingSpecified
- GPU nodes
- 8
- Accelerators
- 16 × 48GB
- Pooled memory
- 768GB
- Interconnect
- 2 × NDR 400Gb/s
- Filesystem
- 400TB NVMe
- Each node
- 2x Intel Xeon 6747P, 512GB DDR5 ECC, 2x L40S 48GB
- Cabinets
- 1
- Deployment
- Rack, in your own room or a colocation
These are the figures the design was specified and tested to, not figures computed from a parts list. A cluster is a network, a filesystem and a node count, and no single build expresses that. The final numbers come from sizing it to your room, your power and your work, and every node in it is measured the usual way.